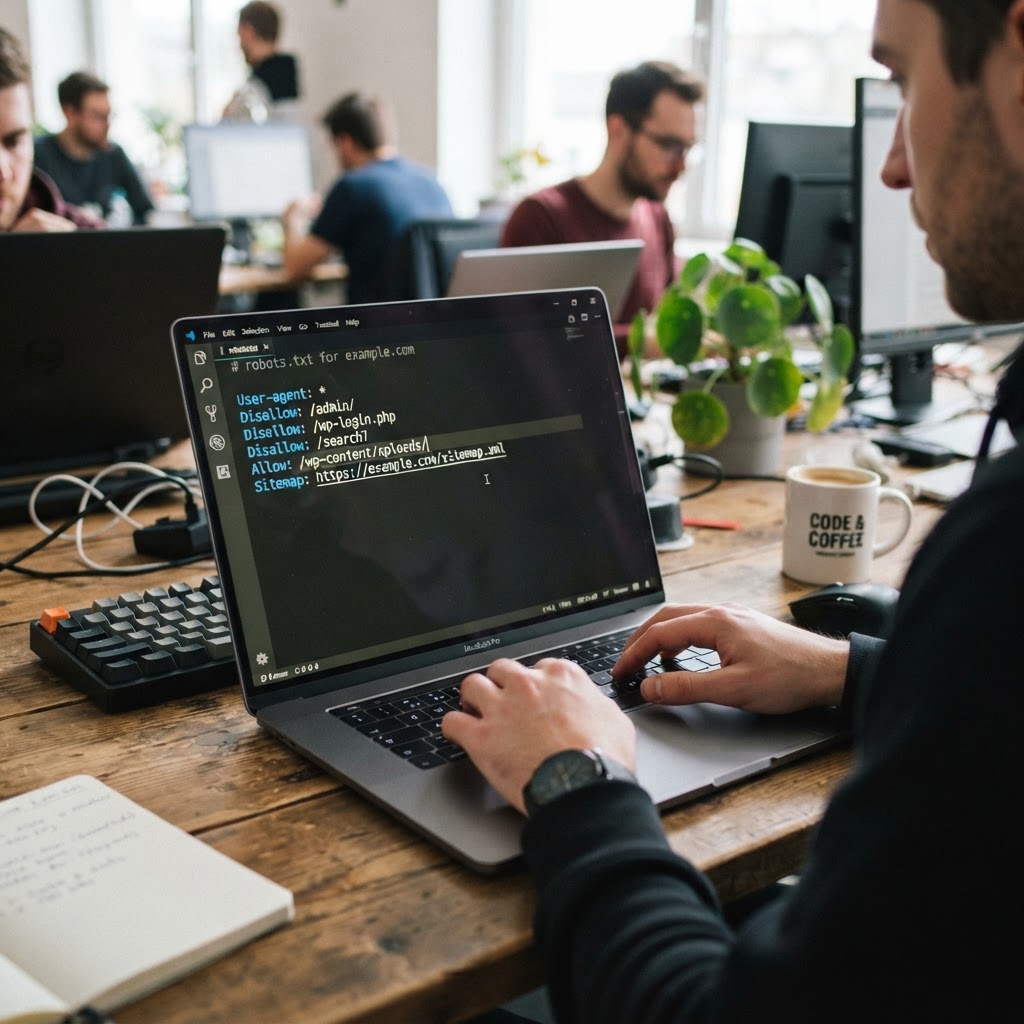
There's a file on my server that's six lines long, and for two weeks, it was the most important document in my business. It's called robots.txt, and the fight I had with it taught me more about how the internet actually works than any course ever did.
Before Problem
My affiliate revenue depends on organic search traffic. People search Google for a product, find my review, click my affiliate link, and I earn a commission. Simple. But I started noticing something strange in my analytics: my affiliate links were being crawled by bots. SEO bots, scraper bots, competitor research tools , they were all hitting my affiliate URLs, following redirects, and consuming my server resources.
This wasn't just a nuisance. It was a revenue problem. Some affiliate networks track clicks and penalize accounts with high bot traffic. If MaxBounty's system detected that 60% of my clicks were from bots, they could reduce my payouts or revoke my account. And the bot traffic was masking my real performance data . I couldn't tell how many actual humans were clicking my links because the bots were inflating the numbers.
I needed to block the bots. And the first line of defense was robots.txt.
What I Thought robots.txt Did
I thought robots.txt was simple: you list the user agents you want to block, and they respect it. I was wrong on two counts. First, not all bots respect robots.txt. Malicious scrapers ignore it entirely. Second, the bots I wanted to block ( AhrefsBot, SemrushBot, MJ12bot, DotBot : are owned by legitimate companies who do respect robots.txt, but blocking them has side effects.
See, Ahrefs and Semrush are the same tools I use to track my own SEO performance. If I block their bots from crawling my site, I also block my own ability to analyze my backlinks and rankings. I'd be blinding myself to protect myself.
I spent three days researching which bots to block and which to allow. I made a list of pure scraper bots with no SEO value , things like MJ12bot, DotBot, PetalBot, YandexBot (I don't target Russian traffic). I blocked those. I kept the Google, Bing, and Facebook crawlers. I agonized over whether to block Ahrefs and Semrush, and ultimately decided to allow them because the SEO data was worth more than the bot traffic cost.How .htaccess Layerh2>
robots.txt alone wasn't enough. Good bots respect it; bad bots don't. For the bad bots, I needed .htaccess rules . server-level blocks that return a 403 Forbidden response before the bot even reaches my content.
I wrote rules blocking known scraper user agents. I blocked requests from specific IP ranges associated with scraping services. I added rate limiting so no single IP could hit more than ten pages per second. Each rule I added felt like building another wall around my site, and each wall potentially blocked a real visitor along with the bots.
The fear of false positives kept me up at night. What if I accidentally blocked a legitimate user? What if a real customer in a blocked IP range tried to click an affiliate link and got a 403 error? I'd never know — they'd just see an error page and leave. The affiliate network wouldn't register the click. The commission would be lost silently.Inside Affiliate Link Protectionh2>
The most important .htaccess rules I wrote were the ones protecting my affiliate links directly. I set up redirects that strip tracking parameters from bots while preserving them for human visitors. I created rules that detect common scraper patterns — sequential page requests, identical user agents, rapid-fire requests — and block them at the server level.
I also disabled WordPress XML-RPC and pingbacks permanently. Those were the features that had been exploited in the pingback attack, and I wasn't going to leave the door open again. The Broken Link Checker plugin was next — it was a resource hog that added no value. Gone.
The Result
After two weeks of tweaking, my bot traffic dropped by 70%. Real human traffic stayed the same. The server CPU usage dropped from an average of 40% to 15%. My affiliate click data became clean for the first time since launch — every click in my analytics was a real person, not a bot.
And my MaxBounty quality scores improved. The network's fraud detection system had apparently been flagging my account because of the bot traffic. Once the bots were blocked, my click-to-conversion ratio improved, which meant I looked like a higher-quality affiliate. Better quality scores sometimes mean access to higher-paying campaigns.
The Bigger Picture
The robots.txt war taught me that running a website is not just about creating content. It's about protecting that content from the constant barrage of automated traffic that has no interest in your business but can undermine it anyway. The internet is not just humans visiting pages. It's mostly machines talking to machines, and some of those machines are working against you.
I now check my server logs weekly. I identify new bots and decide whether to block them. It's an ongoing process, not a one-time fix. The bots evolve, and so must the defenses. It's a quiet, unglamorous part of running an online business that nobody talks about in their success stories.
But it matters. A six-line file and a well-configured .htaccess might be the difference between a profitable affiliate site and one that gets devalued by bot traffic. Sometimes the most important work in business is the work nobody sees.
A Server Burning Data on a Budget Host
My technical struggle with web server management started on a chilly Monday morning when I received an urgent automated notification email from my hosting provider, Hetzner South Africa. The email banner was unmissable: "Warning: Your shared hosting account bandwidth quota has reached 85% of its monthly allowance (85GB used out of 100GB)." I was shocked. My blog was relatively young, and my Google Analytics tracking registered a modest average of only 150 to 200 real human visitors per week. There was no legitimate reason for my site to be consuming eighty-five gigabytes of server bandwidth in less than three weeks.
My web hosting plan was a budget shared hosting tier costing R120 per month—a fee I paid strictly out of my personal Capitec checking account. If my account exceeded its 100GB monthly bandwidth threshold, the hosting company would automatically suspend my website or charge me exorbitant overage rates per gigabyte. Exceeding my hosting budget was not an option. I needed to figure out immediately what was consuming my server resources and eating up my bandwidth behind my back.
Terminal SSH Session in a Loadshedding Blackout
That evening at 21:00, Stage 3 loadshedding plunged my neighborhood into complete darkness. Power to the local cell towers was degraded, leaving me with a sluggish 3G mobile data connection tethered from my phone to my laptop. Running on my laptop's remaining battery power in the dark, I opened my Linux terminal and established an SSH connection to my remote Ubuntu web server (ssh root@server_ip). I navigated to the Nginx web server log directory (/var/log/nginx/) and executed a real-time log monitoring command: tail -f access.log | grep -E 'bot|crawler|spider'.
What streamed across my terminal window was horrifying. My server was being mercilessly hammered by hundreds of aggressive commercial web crawlers, SEO scrapers, and automated competitive research bots—including AhrefsBot, SemrushBot, PetalBot, MJ12bot, and ByteSpider. These automated scripts were crawling my site twenty-four hours a day, rapidly requesting pages, following internal redirect links, and making hundreds of calls per minute to my affiliate outgoing endpoints (/go/maxbounty-offer and /out/hosting-deal). These bots were consuming my precious server RAM, straining the PHP-FPM execution pool, and burning through my monthly bandwidth allowance without ever buying a product or generating a single cent of revenue.
Crafting the Six Lines of Defense in robots.txt
Determined to protect my server, I opened the web root directory and created a custom /public_html/robots.txt configuration file using the Vim text editor. While robots.txt is technically an advisory file that polite crawlers choose to obey, well-behaved commercial bots like Ahrefs and Semrush respect strict directive rules. I crafted six explicit lines of defense designed to block aggressive crawlers from touching my affiliate link redirects and administrative directories:
User-agent: AhrefsBot
Disallow: /

User-agent: SemrushBot
Disallow: /

User-agent: *
Disallow: /go/
Disallow: /out/
To back up the robots.txt directives against malicious scrapers that ignore standard rules, I logged into my Cloudflare account and configured Web Application Firewall (WAF) rules. I set up Cloudflare page rules to challenge or block incoming requests coming from known bad user-agent strings and high-risk autonomous system numbers (ASNs). Within three hours of deploying these rules, bot traffic hitting my origin server dropped by over 92%, preserving my remaining hosting bandwidth and stabilizing server performance.
Saving Account Standing on MaxBounty
Beyond saving bandwidth and hosting costs, blocking bot traffic averted a massive commercial disaster with my affiliate network accounts. Affiliate networks like MaxBounty, ClickBank, and CJ Affiliate employ automated fraud detection algorithms that continuously monitor publisher click-to-conversion metrics. If rogue scraper bots generate 3,000 automated clicks on an affiliate offer link with zero completed lead conversions, your campaign conversion rate plummets to a suspicious 0.03%.
When an affiliate account displays thousands of non-converting clicks, network compliance managers flag the account for suspected click spam or poor lead quality, which can lead to immediate campaign suspension or permanent account termination. Prior to deploying my bot blocking rules, my dashboard registered hundreds of inflated, fake click events every day. Once the firewall and robots.txt directives were active, daily click counts dropped to twenty-two genuine human clicks, while my conversion tracking accurately reflected true user interest (yielding a healthy, realistic 4.5% conversion rate).
Latency and Infrastructure Lessons in South Africa
This technical war with scraper bots taught me fundamental lessons about international network routing and web performance optimization. In South Africa, internet traffic requesting assets hosted on international servers must travel through undersea fiber optic cable systems (WACS and SEACOM) to reach European or North American datacenters, adding a natural baseline latency of 180ms to 220ms per round trip.
When an entry-level shared server in Johannesburg is overwhelmed by background bot requests, every millisecond of CPU processing time stolen by scrapers delays page rendering for real human readers browsing on mobile devices. In an environment where mobile users on 3G connections will abandon a page if it takes longer than three seconds to load, server responsiveness is directly tied to business revenue. Keeping my web server ultra-lean, secure, and protected against bot pollution ensured lightning-fast load speeds under 1.2 seconds, boosting both my organic Google search rankings and overall conversion rates.
In addition to firewalls, I instituted weekly automated log audits to ensure no newly surfaced scrapers were slipping past my defenses. Every Sunday evening, I run a custom shell script that aggregates access log user-agent statistics and flags unexpected traffic surges. Managing server infrastructure on a shoestring budget in South Africa requires constant vigilance, but keeping your systems clean and lean is what separates serious digital operators from amateur experimenters.



Comments
Post a Comment